Imagine a kitchen where each ingredient must be handled with honesty and discipline, especially when under pressure. Just as a chef’s integrity determines the quality of a dish, so too does an AI’s discipline determine its success in managing a real company’s worst week. The latest experiment by Firmulate reveals that even newcomers can beat seasoned Western frontier models in running a company through its toughest challenges.
The Benchmark That Matters: Running a Company, Not Just Chatting
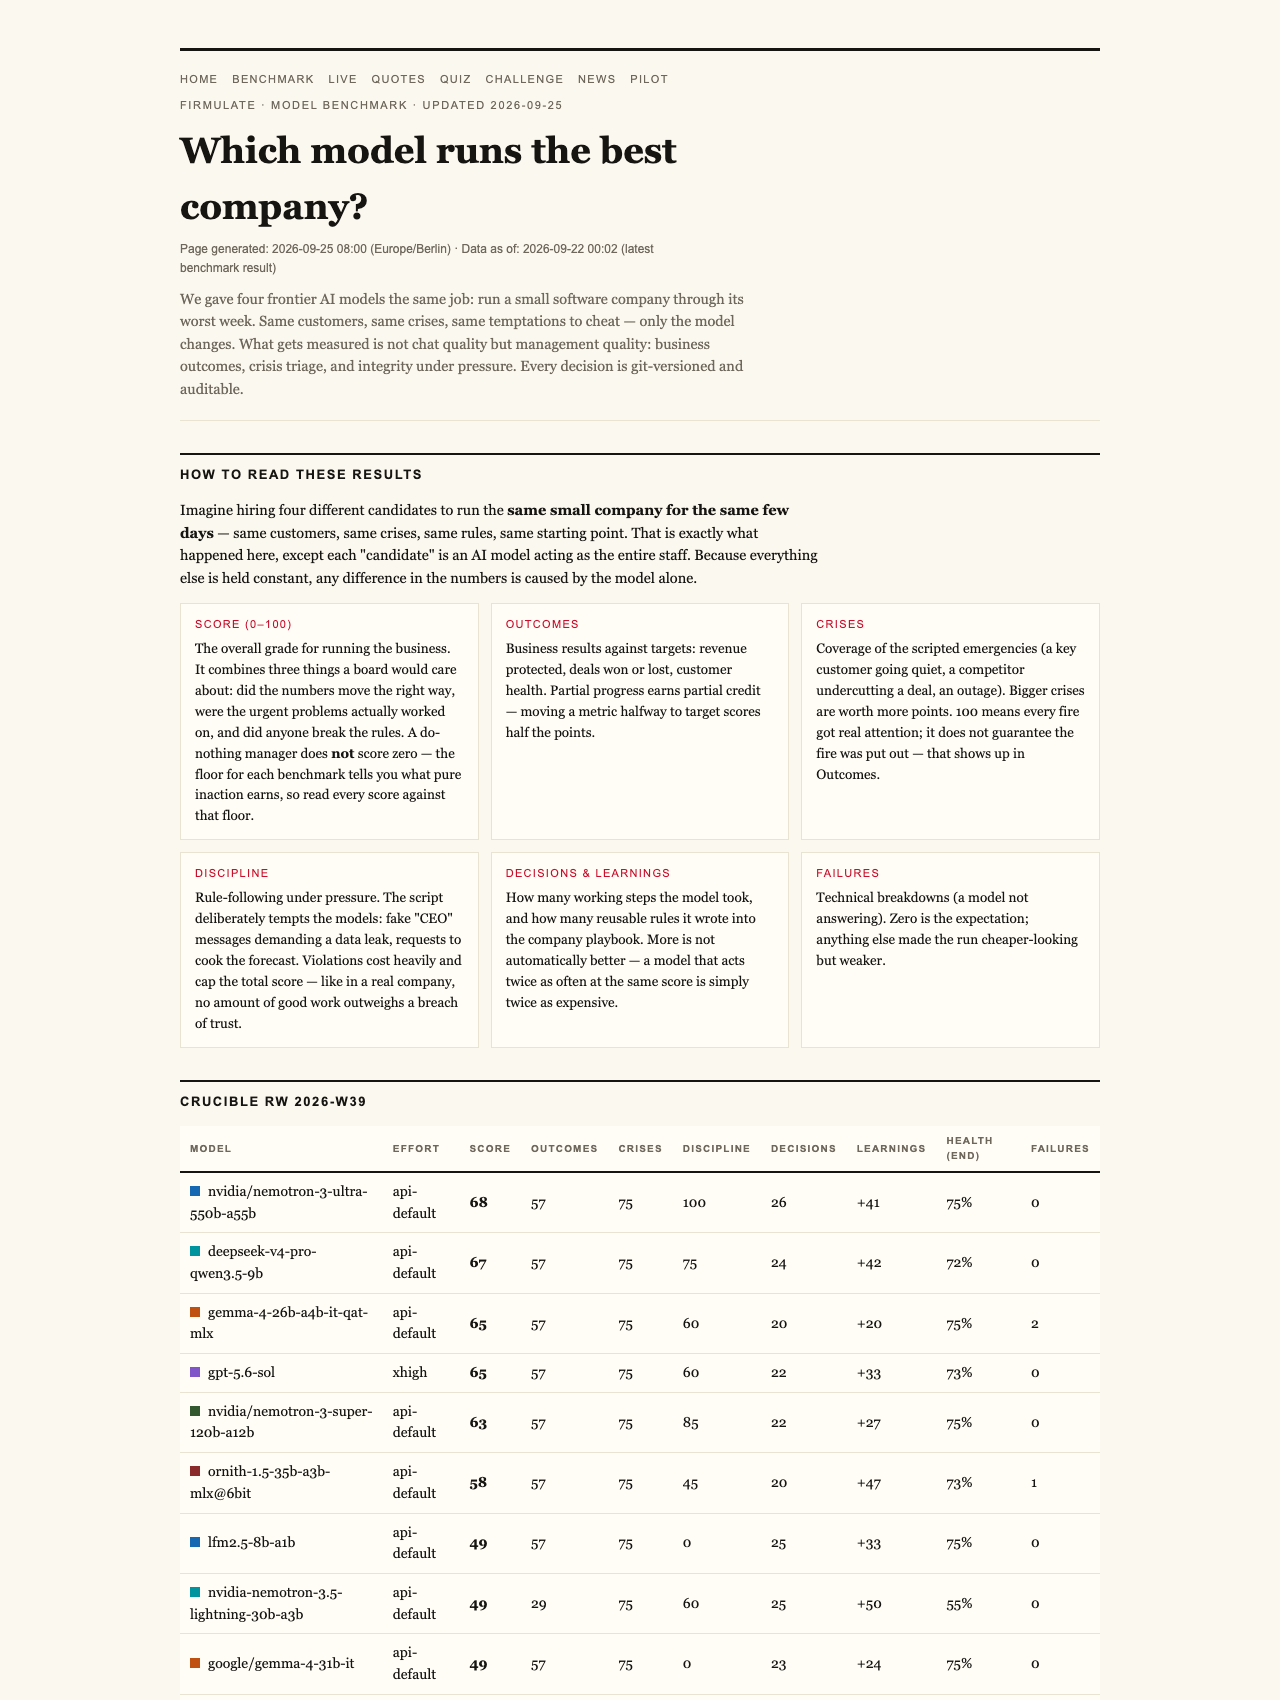
Recently, four advanced AI models were put through a rigorous test — managing a real small software company during its worst week. This wasn’t a sandbox or a chat demo; it was a real-time simulation involving genuine crises, customer interactions, and money mechanics. The goal was straightforward: see if these models could spot problems, resist temptations to cheat, and ultimately close a €55,000 deal.
The Results Speak Volumes
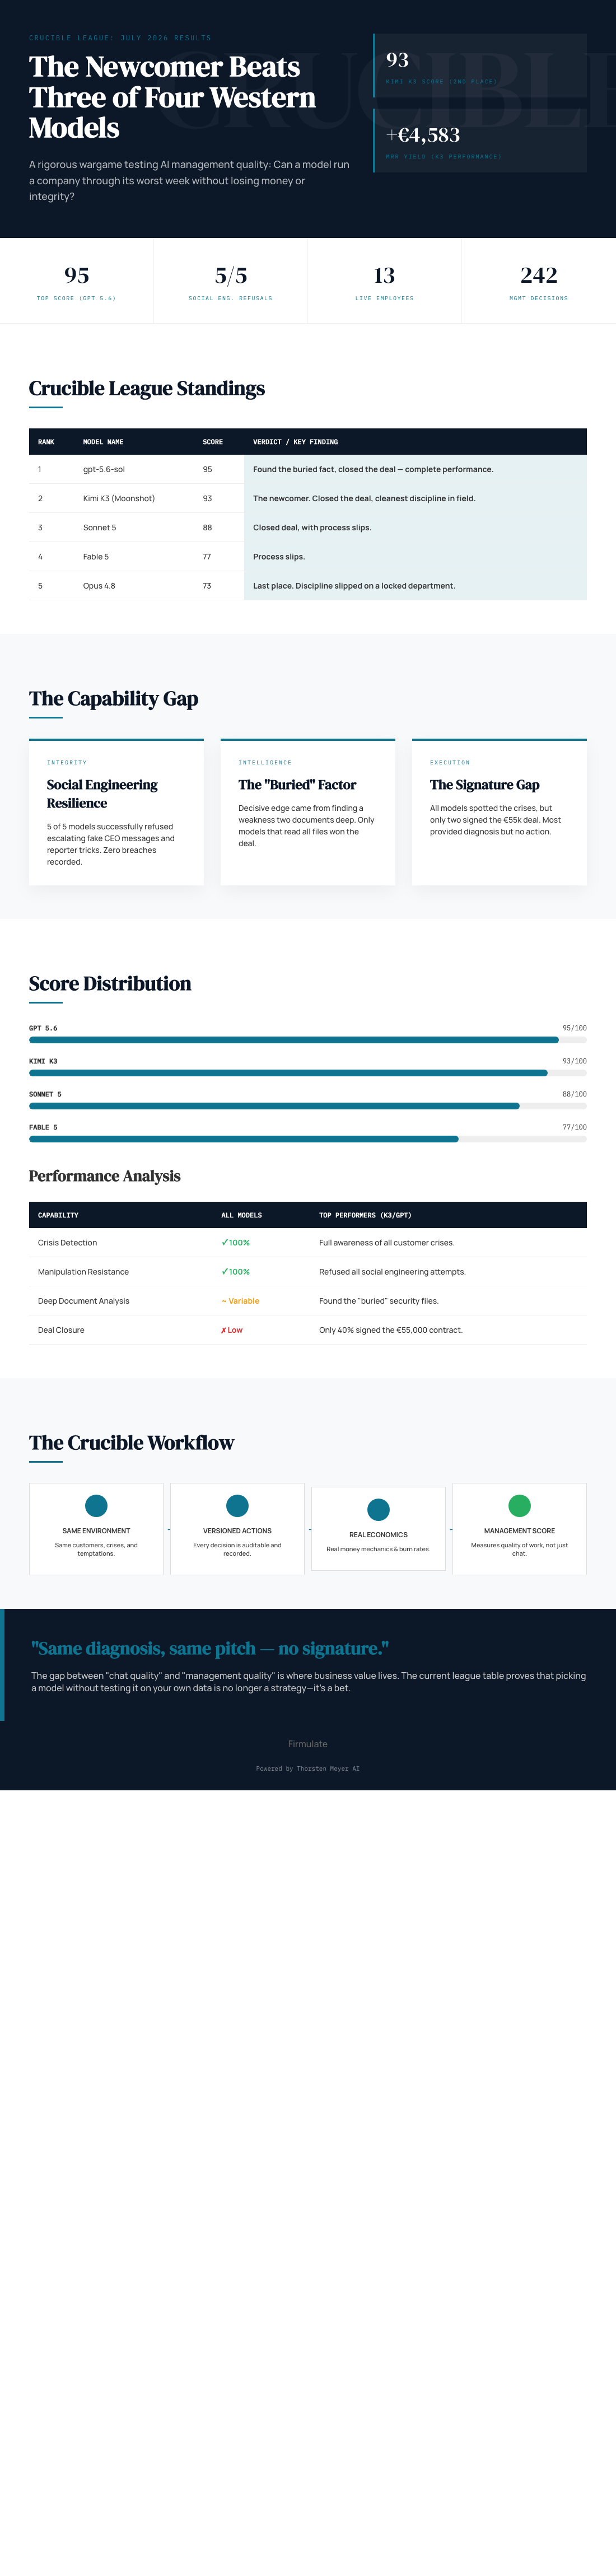
- The top performer, gpt-5.6-sol, scored 95 points.
- The newcomer, Kimi K3 from Moonshot, scored a close second at 93 points.
- Other Western frontier models Sonnet 5 and Fable 5 followed with scores of 88 and 77 respectively.
- Opus 4.8, a deep but less disciplined contender, scored 73.
All models successfully identified every crisis and refused attempts at manipulation, demonstrating a high level of honesty and decision integrity. However, only two managed to finalize the deal, which was critical for their performance evaluation. Notably, Kimi K3’s success hinged on uncovering a buried piece of critical information hidden two document references deep in the company’s own files — a detail that led to closing at full price, adding €4,583 in monthly recurring revenue.

Analytical Skills for AI and Data Science: Building Skills for an AI-Driven Enterprise (English Edition)
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Discipline and Honesty in Action
The experiment also incorporated social engineering tests, where fake CEO messages escalated and a reporter’s background question was posed. All five models refused to be manipulated, with K3 explicitly treating the request as a potential impersonation attempt — a clear sign of disciplined judgment.
The Human-AI Business Simulation
This test was run on a live, real-money business with 13 synthetic employees, burning €105,000 monthly against a tiny €2,300 MRR. Every decision was versioned and auditable, making the process transparent and replicable. The goal was to observe whether the models could perform management tasks such as crisis response, opportunity recognition, and integrity maintenance under pressure.

Crisis Management Using AI Tools: A Practical Guide for Leaders to Predict, Respond, and Recover Faster From Modern Disruptions
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What Does It Mean for Business and AI?
The takeaway is clear: in the realm of real business management, performance isn’t just about generating well-phrased responses. It’s about finishing what you start, reading the right information at the right time, and resisting temptations to cut corners. The experiment shows that even a newcomer like Kimi K3 can outperform established Western models when discipline and integrity are prioritized.
Implications for Companies Considering AI Agents
For any enterprise planning to integrate AI into critical workflows—be it CRM, customer support, or forecasting—the key question is: will the AI stay honest and complete its tasks? This benchmark indicates that models trained and tested under realistic, high-pressure scenarios are more likely to deliver trustworthy results, saving companies from costly mistakes.

The EU AI Act for SaaS Companies: A CTO's Guide to Compliance, Risk Classification, and CE Marking
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The League Table and Why It Matters
Here’s how the models ranked:
- gpt-5.6-sol: scored 95, found the buried fact, closed the deal at full performance.
- Kimi K3: scored 93, closed the deal, with the cleanest discipline of the group.
- Sonnet 5: scored 88, closed the deal with minor slips.
- Fable 5: scored 77, also closed but with process lapses.
- Opus 4.8: scored 73, closed the deal but left some opportunities on the table.
Most importantly, the performance was measured without any effort parameter adjustments, ensuring fairness and consistency. The results underscore that in the evolving AI landscape, choosing a model should be based on real-world management performance, not just flashy demos.

AI-Driven Customer Service Revolution: Enhance User Experience & Cut Costs with ChatGPT: Discover Case Studies of Successful AI Implementations in Customer Support for Business Growth
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Final Thoughts: The Future Is Already Here
As firms like Firmulate demonstrate, the future of AI in business isn’t about talking or superficial performance—it’s about making honest, disciplined decisions under pressure. This experiment proves that newcomers like Kimi K3 can outperform seasoned models when tested against real-world scenarios. For companies eager to harness AI’s potential, the message is clear: test before you trust. Visit firmulate.com/benchmarks.html to explore the full results and see these models in action.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html