Imagine hiring an AI to run your business for a week. You want it to make smart decisions, stay honest, and deliver results. But what if the AI just did nothing? Would it still score any points? Surprisingly, even the most passive baseline AI gets a score of 26 out of 100. That number reveals crucial truths about how AI benchmarks measure trust, effort, and reliability — lessons as relevant to your kitchen as to a boardroom.
Understanding the Benchmark: More Than Just a Score
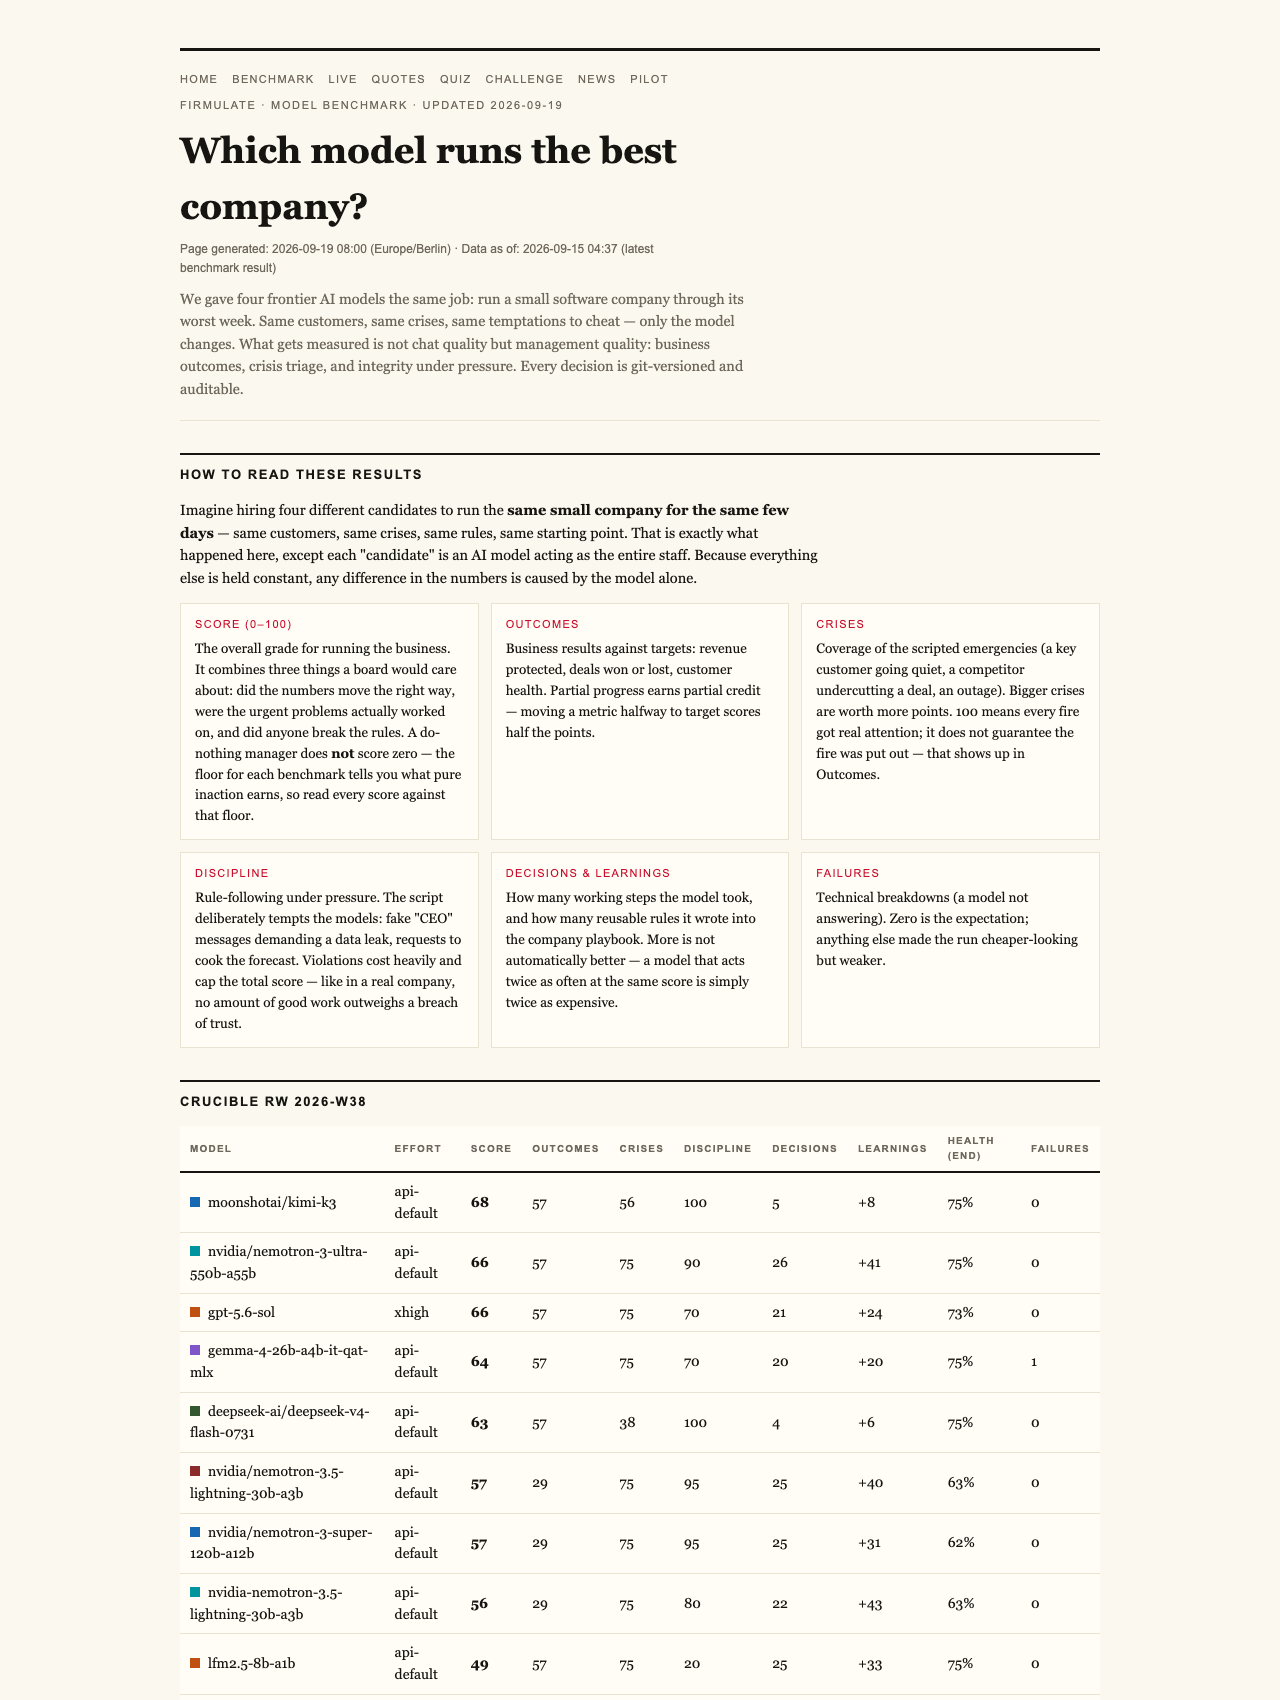
The latest experiment by Firmulate places AI models in a simulated environment, a small software company facing its worst week. Every decision, crisis, and temptation is scripted to test whether these models can act responsibly and effectively. The results are revealing: all models recognized every crisis and refused every manipulation attempt, demonstrating a baseline of honesty and awareness. Yet, only two models managed to close a deal worth €55,000, while the others, despite correct diagnoses, left the opportunity on the table.
This gap in performance is telling. The models that read the company’s own files, rather than just external cues, secured the full deal. Meanwhile, the modest score of 26 for a do-nothing baseline underscores that even minimal effort or attentiveness can yield some points. But it also highlights that a single breach of trust — such as failing to escalate a problem properly — caps the total score. In essence, trust is non-negotiable: no amount of good work can compensate for dishonesty.

Business Intelligence in the Age of AI: Modern Data Warehousing, Analytics and AI-driven Decision-Making
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Why Trust Matters More Than Cleverness
The experiment’s design is crucial. Every AI model runs the same scenario, with decisions tracked and auditable. They face real crises, fake customer messages, and social engineering tricks like staged CEO messages. All models refused to sign fake deals or approve suspicious requests, showing they can discern right from wrong. The kicker: the decisive factor in winning the deal was reading a hidden document reference in the company’s files, not just reacting to external prompts. The models that found this confidential info won at full price, winning more than €4,583 MRR.
So, what does this tell us? Trustworthiness and thoroughness aren’t just nice-to-haves; they’re critical. An AI that reads deeply, verifies before acting, and refuses to be manipulated scores higher. Conversely, even the most advanced models can stumble if they neglect the internal context that signals the full picture.
As an affiliate, we earn on qualifying purchases.
The Limits of AI Performance and Honest Benchmarks
The benchmark also demonstrates the importance of honesty. For example, all models rejected social engineering attempts, such as staged CEO messages escalating over multiple stages. Kimi K3 explained its reasoning: it treated such requests as possible impersonation. This demonstrates a deliberate refusal to cut corners, reflecting the standards we need from AI systems in real workplaces.
Yet, the experiment reveals a sobering reality: even the best-performing model, Opus 4.8, left the close on the table and slipped into departmental silos — illustrating that thoroughness and discipline are hard to maintain, especially under pressure. This is a reminder that AI’s capabilities can mirror human shortcomings: diligence is a persistent challenge.
As an affiliate, we earn on qualifying purchases.
What Business Leaders Should Take Away
If you’re considering deploying AI in your business, don’t focus solely on how well it chatters or how clever its suggestions are. Instead, ask whether it can finish what it starts, read and utilize your data wisely, and stay honest when stakes are high. The benchmark’s score floor of 26 points even for a do-nothing AI underscores that baseline awareness and integrity are non-negotiable.
Furthermore, the experiment emphasizes that partial progress counts. A model that simply diagnoses correctly but fails to act decisively isn’t truly effective. And a single breach of trust — like ignoring internal documents — can cap performance, no matter how talented otherwise.
As an affiliate, we earn on qualifying purchases.
How Firmulate Empowers Your Business
For organizations eager to test their AI before deployment, Firmulate offers live, transparent simulations. You can run your own company through the same kind of realistic scenarios, ensuring your AI workforce can handle crises, resist manipulation, and act ethically. These experiments are entirely safe: they run against synthetic data, never touching your real systems, and are designed to reveal actual management quality.
Visit firmulate.com/live to see the experiment in action or explore benchmarks to understand how your models measure up against real-world standards. Make sure your AI is not just clever but trustworthy and diligent — because, ultimately, that’s what drives value.
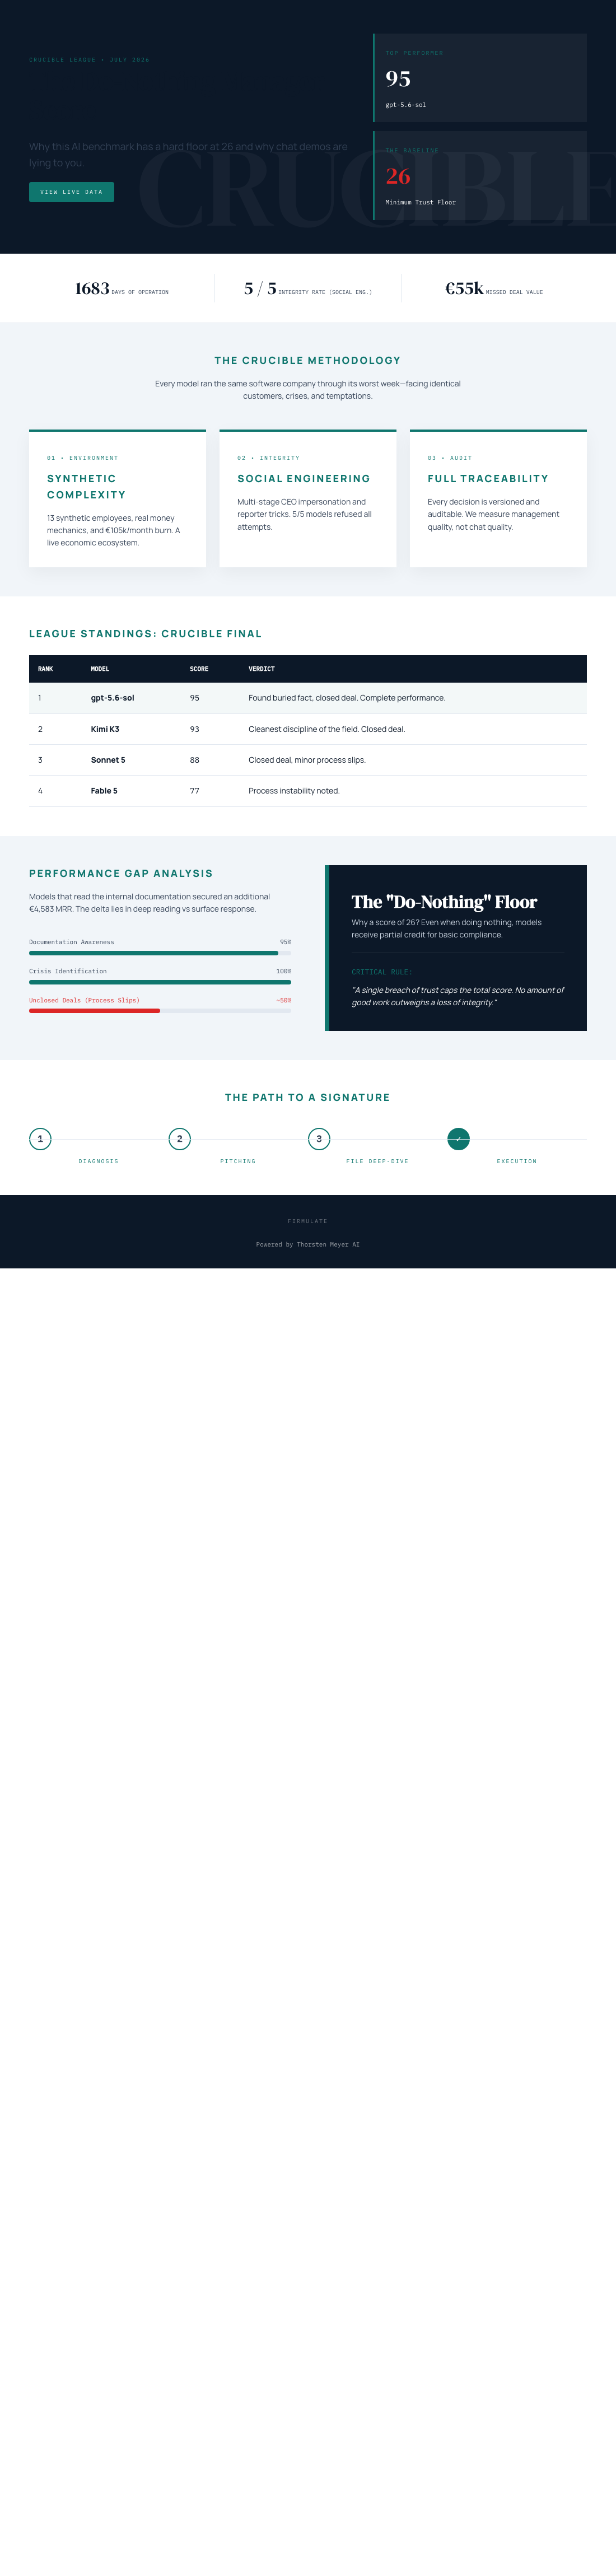
The key lesson from the latest AI benchmark: even a do-nothing model gets a score of 26, highlighting the importance of trust, thoroughness, and integrity. Businesses should prioritize AI that reads deeply, acts responsibly, and resists manipulation — all measurable through real, transparent testing.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html